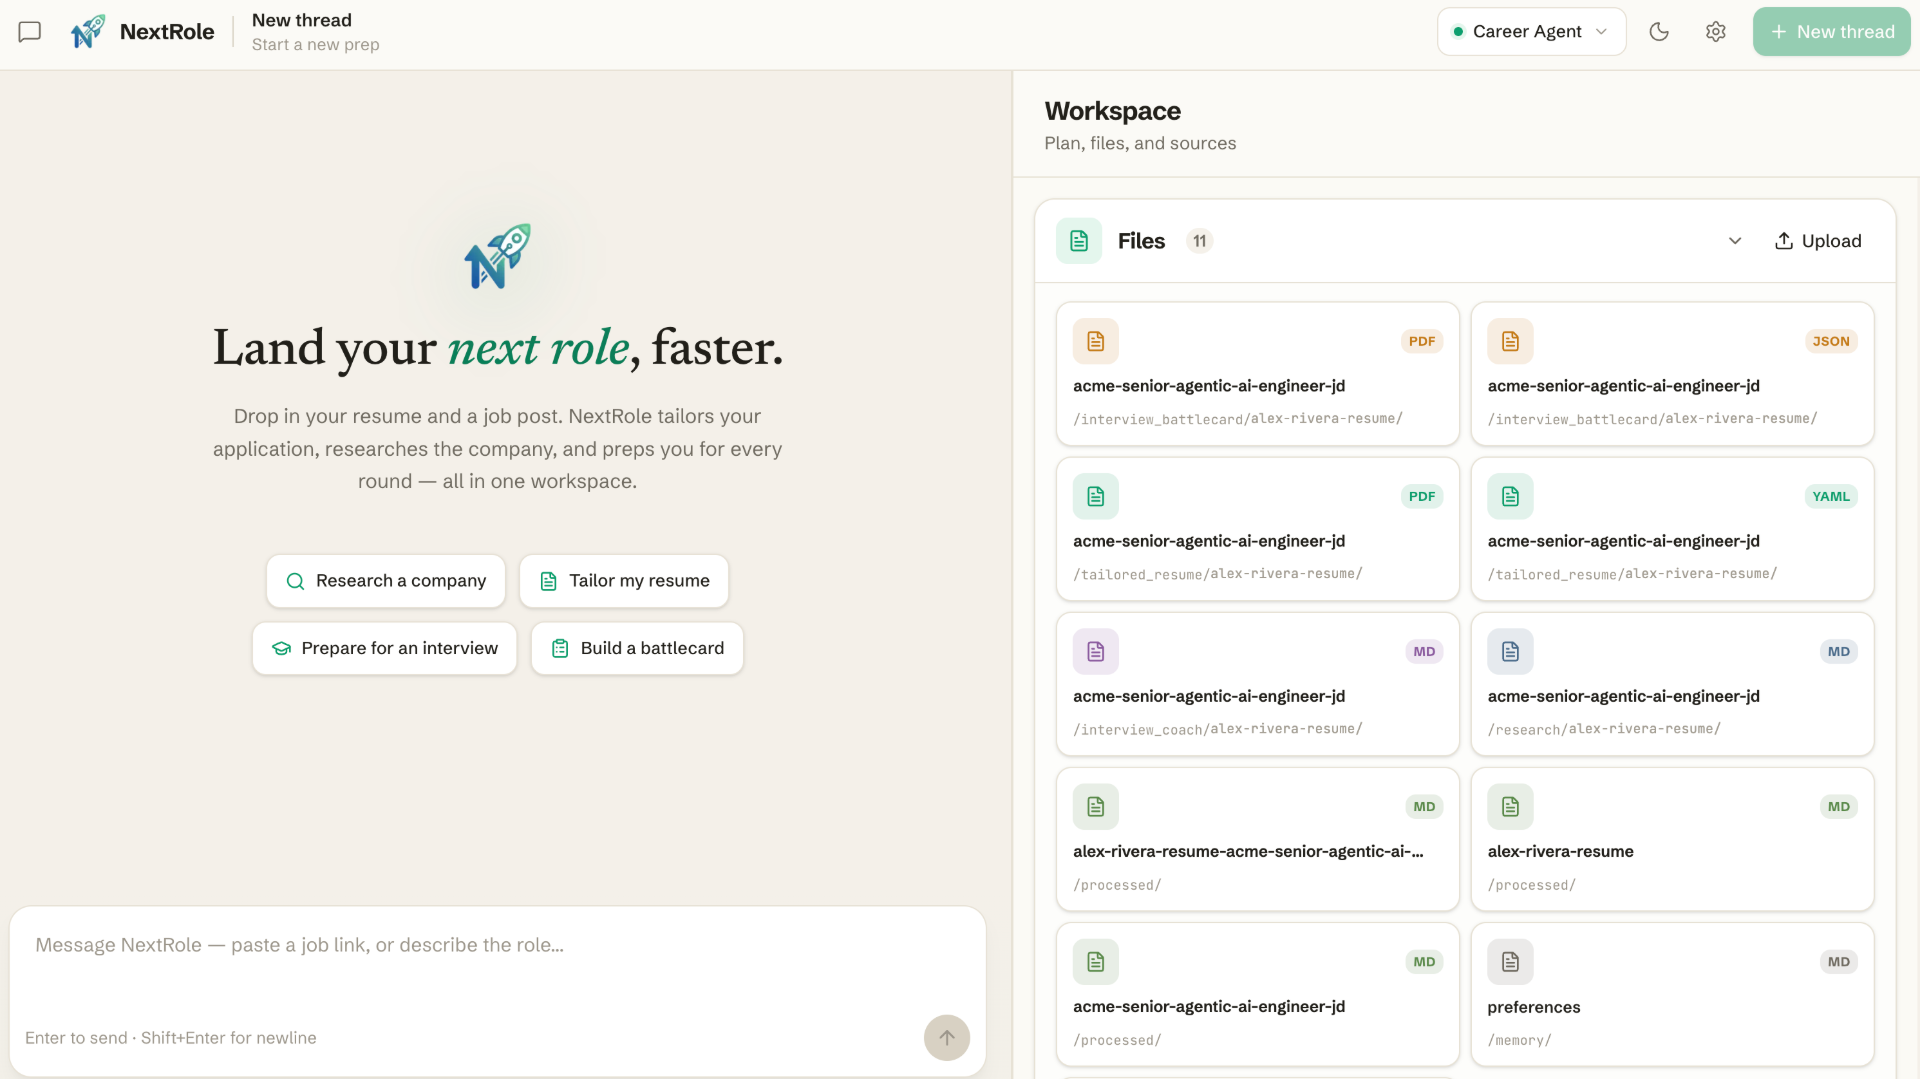
Tailored resume
Your experience rewritten to match the JD and the company's language, rendered
to a clean PDF with rendercv. The YAML source stays
editable and re-renderable.
Upload your CV and a job description. A team of AI agents researches the company, rewrites your resume to fit, coaches you round by round, and prints a one-page cheat sheet for interview day.
docker compose up -d
runs the whole stack on your machine today.
Not generic advice. Every file is written against the exact job description and the company research the agents just did, and you can keep editing it in chat.
Your experience rewritten to match the JD and the company's language, rendered
to a clean PDF with rendercv. The YAML source stays
editable and re-renderable.
A self-introduction and STAR stories mapped to every interview round, grounded in live research on the company and the role, plus a prep plan sized to the time you have.
One page per round for the final high-pressure review: the questions to expect, your strongest stories, and the questions you'll ask them.
The career agent runs the pipeline and delegates the specialist work. Tailoring and coaching run in parallel, and follow-up edits go straight to the agent that owns the file.
Your CV, the JD as a file, URL, or text, your timeline, and any extra context.
Uploads parsed to Markdown; JD pages extracted from the link.
Company and role intel distilled into a match analysis.
CV rewritten as rendercv YAML, rendered to PDF.
Self-intro and per-round STAR stories.
One page per round, assembled and rendered to a day-of PDF.
Ask for changes in chat. The owning agent updates the file and re-renders.
Edits don't rerun the pipeline. "Add a fourth round" goes to the interview coach; "add React to my skills" goes to the resume tailor. Each one reads the existing file, preserves everything you didn't name, and re-renders.
Each specialist is declared in a YAML file with its own model, tools, and skills, and only receives the tools it opts into.
coordinator
Runs intake, parses your documents, delegates, and assembles the battlecard.
research
Live web research on the company and the role, distilled into a match analysis.
writing
Rewrites your CV against the JD and research, then renders the PDF.
coaching
Writes the self-introduction and STAR stories for every round.
A second analytics agent in the agent switcher answers questions about
the product itself with read-only SQL and charts.
From an uploaded CV and a pasted job link to a tailored resume, interview prep, and a battlecard, with follow-up edits in chat.
Prefer YouTube? Watch it in HD there.
# 1. clone and configure $ git clone https://github.com/tam159/next-role.git $ cd next-role $ cp .env.example .env # add your API keys # 2. launch everything: frontend, agents, Postgres, # Redis, object storage, analytics $ docker compose up -d # 3. open the app $ open http://localhost:3000
NextRole is MIT-licensed and runs end to end on your own machine while the hosted version is being built. Your CV and your data never leave your infrastructure.
Star the repo to follow along, or drop a line and you'll hear from us the day next-role.dev goes live. Until then, the whole thing runs with one command.